Bugs in software have been around for as long as software itself, and they are the key reason why software testing even exists. However, while every software engineer is familiar with bugs, the definitions can differ widely. Most commonly, bugs are seen as a coding mistake, but in reality, QAs spend most of their time dealing with bugs that stem from requirements, environments, or conditions that cannot be reproduced.
With this guide, we want to eliminate the confusion. Find out what software bugs really are, where they come from, learn about the most widespread types of software bugs, and whether bugs can be prevented.
Key Takeaways
A software bug is any deviation between what the software does and what it was specified to do.
Domain-specific bugs pass generic test suites because the test cases don’t know the industry rules the code serves.
Code-level checks like static analysis and unit tests address only about a third of where bugs come from.
Severity measures how much damage a bug does, priority measures how soon it needs fixing, and the two can point in opposite directions.
What Is a Software Bug?
A software bug is any deviation between what the software does and what it was specified to do. Contrary to what some believe, a bug can appear at any stage of the software development lifecycle, and many appear before even a single line of code has been written.
Words by
Mykhailo Tomara, QA Lead
“Bugs can be introduced at the stage when requirements are written because of inconsistencies and just mistakes. If left unattended, they would make their way into product features later. That is why we always recommend starting the QA process at the earliest SDLC phase.”
Bug vs. defect vs. error vs. failure
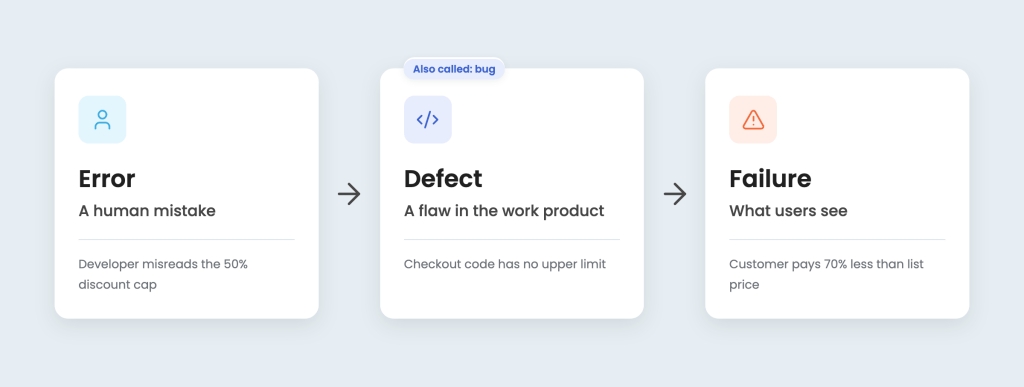
The four terms can seem like synonyms that refer to the same concept, but what they do instead is describe one chain of events, from a human mistake to a problem someone can see. The ISTQB glossary, the reference most QA teams work from, treats bug and defect as synonyms. Teams that separate the two usually reserve “defect” for a confirmed deviation from requirements and use “bug” as the everyday label on a ticket.
Term
What it means
Who usually finds it
Example (one chain)
Error
A human mistake made while specifying or coding
Developers and reviewers
A developer misreads the requirement that discounts cap at 50%
Defect
A flaw in the work product that makes it deviate from requirements
QA engineers and static analysis tools
The checkout code applies discounts with no upper limit
Bug
The everyday name for a defect, used in tickets and bug trackers
Anyone who files a report
Ticket: “Discount over 50% accepted at checkout”
Failure
A visible event where the software system does not perform as required
End users and production monitoring
A customer stacks two coupons and pays 70% less than the list price
The chain explains why root-cause work matters. A team that fixes only the failure, without tracing the error behind it, tends to ship a new bug in the same area within a few releases.
Why software bugs matter: Impact and real-world examples
The cost of a software bug grows the further it travels from the line of code that caused it. The Consortium for Information & Software Quality estimated that poor software quality costs the US economy at least $2.41 trillion a year in its last report.
Two real-world examples show how far a single defect can reach:
CrowdStrike, July 2024. A content update for the Falcon sensor passed 21 input fields to code that expected 20. The out-of-bounds memory read that followed crashed about 8.5 million Windows devices, according to Microsoft, and disrupted airlines and hospitals worldwide.
Knight Capital, August 2012. A deployment pushed new trading code to seven of eight servers. On the eighth, a repurposed flag reactivated retired code, and the firm lost more than $460 million in about 45 minutes, according to the SEC.
Neither bug was exotic. One was a boundary error, and the other a process gap in deployment — both ordinary categories covered later in this article.
Don’t let bugs stand in the way of your product’s success
There are different types of software bugs, and different methods to categorize them, but the most common one is by how the bugs show up: this includes functional, logical, syntax, calculation, boundary, performance, security, compatibility, usability, integration, concurrency, and regression bugs. Here is what those bugs can look like in practice and which kind of testing exists to catch them.
Bug type
How it shows up
Example
Testing that catches it
Functional bug
A feature does not do what the requirements describe
The “Forgot password” link sends no email
Functional testing
Logical bug
Code runs without errors but follows the wrong reasoning, so the output is wrong
Loyalty points are added before a refund is subtracted
Unit testing and code review
Syntax bug
Code breaks the rules of the language and fails to compile or crashes on load
A missing bracket in a JavaScript file blanks the checkout page
Compilers, linters, and CI build checks
Calculation bug
A formula or rounding rule produces wrong numbers
Currency conversion rounds each line item instead of the total, so invoices are off by a cent
Unit testing with edge-case values
Boundary (out-of-bounds) bug
Input at or beyond the edge of an allowed range triggers unexpected behavior
A field limited to 1-255 accepts 256; the 2024 CrowdStrike outage was an out-of-bounds read
Boundary value analysis within functional testing
Performance bug
Response times degrade or resources run out under load or large data volumes
Search takes nine seconds once the catalog passes 100,000 items
Performance testing
Security bug
A flaw lets someone reach data or actions they should not have access to
An API returns another user’s order history when the ID in the URL changes
Penetration testing
Compatibility bug
The software application behaves differently across browsers or devices
A date picker works in Chrome but freezes in Safari on iOS
Compatibility testing
Usability bug
The software works as specified but confuses or slows down users
An error message reads “Error 4012” with no next step
Usability testing
Integration bug
Software components or third-party services exchange data incorrectly
A payment gateway renames a response field, and orders stay “pending”
Integration testing and API testing
Concurrency bug
Parallel threads or users change shared data at the same moment and corrupt it; often hard to reproduce
Two users book the last seat simultaneously, and both get confirmations
Load testing plus code review of shared state
Regression bug
A code change breaks something that worked before
A UI library update breaks the mobile navigation menu
Regression testing, usually an automated regression test suite in CI
Most bugs affect more than one row. A concurrency bug can surface as a functional failure, and a security bug often starts as a boundary error. Concurrency bugs also overlap with the hardest-to-reproduce category covered in the next section.
Words by
Michael Tomara, QA Lead, TestFort
“The classification of bugs may be more or less important depending on a specific project and a specific situation. If it is an MVP or something belonging to a narrow niche, identifying a newly found bug as a performance issue may decrease its priority. If a new version of a successful product is released, finding a regression bug triggers a major alert.”
Domain-specific bugs sit outside generic taxonomies because they break industry rules rather than code rules. In fintech, a rounding rule might push a transaction past a regulatory reporting threshold. In healthcare, a dosage field might accept milligrams where the label uses micrograms. These bugs pass generic test suites because the test cases only know what the code does and nothing about the rules it serves.
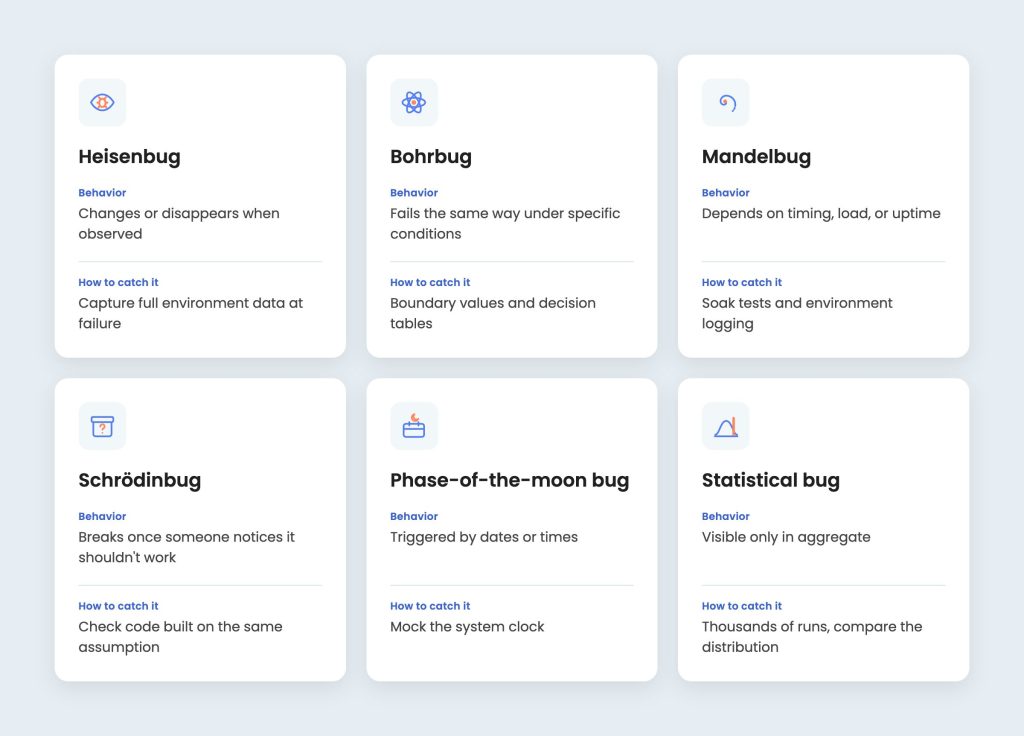
Tricky Bug Types: Heisenbugs, Bohrbugs, Mandelbugs, and Others
When testers find bugs, they can usually fit the bugs into the “reproduce, fix, verify” framework. But what if the bug happens to go outside the predefined parameters? That’s where rare bugs come from. These bugs are often hard to spot and even harder to reproduce, which makes them all the more important not to miss.
Heisenbug
A Heisenbug disappears or changes behavior when someone tries to observe it. Attaching a debugger or adding log statements shifts timing or memory layout just enough to hide it. Race conditions and uninitialized memory are the usual causes.
Jim Gray’s 1985 study of failures in Tandem systems found that faults in production software are often soft, or transient. That is the main reason a heisenbug might pass every test run and still fail for customers. Testers capture full environment data at the moment of failure, the same approach used for a bug the customer can’t reproduce.
Bohrbug
A Bohrbug fails the same way every time under a specific set of conditions, like the stable electron orbits in Bohr’s atom model. Once found, it is the easiest of these bugs to fix. The hard part is finding the conditions, which often sit in rarely executed code paths such as error handlers or year-end routines. Systematic test design, using techniques like boundary values and decision tables, is how testers detect bugs of this kind.
Mandelbug
A mandelbug has causes so complex that its behavior looks chaotic. Michael Grottke and Kishor Trivedi define it as a fault whose activation depends on the system environment, such as timing or uptime. Their classification treats aging-related bugs, like memory leaks, as a subtype.
Their 2007 paper opens with the 1991 Patriot missile failure in Dhahran, where a timing error grew the longer the system ran. Long-running soak tests and detailed environment logging help teams catch mandelbugs before users do.
Schrödinbug
A Schrödinbug stays hidden until someone reads the code, realizes it should never have worked, and it promptly stops working. The term comes from programmer folklore. The usual explanation is a latent defect masked by conditions that happened to change around the time of the review. When one turns up, testers check every other component built on the same flawed assumption.
Phase-of-the-moon and statistical bugs
A phase-of-the-moon bug depends on a parameter that seems irrelevant, most often the date or time. Leap days and daylight saving switches are classic triggers. Microsoft’s 30GB Zune players froze on December 31, 2008, because of a leap-year bug in the clock driver. Testers catch these by mocking the system clock and running date-sensitive scenarios.
A statistical bug shows up only in aggregate, such as a shuffle feature that plays some songs more often than others. A single run looks fine, so tests need thousands of iterations and a comparison of the resulting distribution.
Big or small — we’ll make sure bugs don’t threaten your successful releases
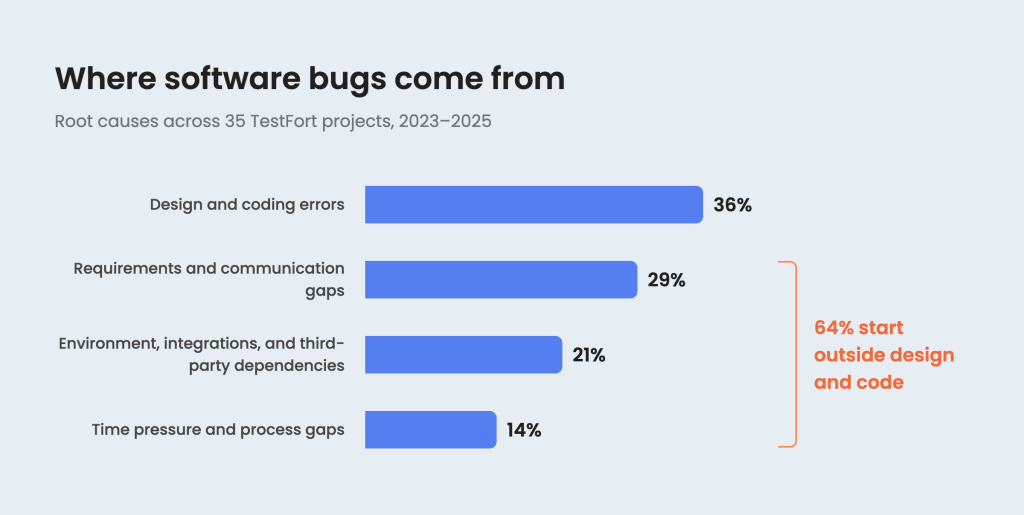
The causes of software bugs look different once someone counts them. In about 5,200 bugs from 35 TestFort projects, observed between 2023 and 2025, 64% began outside design and code. The rest of the software development process, from requirements to release planning, is where those bugs arise. Here is what it looks like from our practice.
Design and coding errors: 36%
The largest share covers mistakes made while turning a design into working code. Most are plain human error, like an off-by-one loop or a null value nobody planned for. Design flaws in this category surface later and cost more to fix. A data model that can’t handle concurrent edits, for example, spreads into every feature built on top of it. Code-level checks such as static analysis and unit tests target this category directly, and they are the only ones that do.
Requirements and communication gaps: 29%
Nearly three in ten bugs trace back to what the team agreed to build. Acceptance criteria that read one way to a product owner and another way to a developer produce code that works exactly as written and still fails review. Requirements that change mid-sprint cause a quieter version of the same problem when nobody updates the test scope, because old test cases keep checking yesterday’s behavior. These bugs arise when software matches its spec and the spec misses what users need.
Words by
Mykhailo Tomara, QA Lead
“Testing requirements before features are built and analyzing acceptance criteria of a ticket before testing it – these activities should be a part of your QA process.”
Environments, integrations, and third-party dependencies: 21%
About a fifth of bugs come from outside the codebase the team controls. A browser update changes how a layout renders, or a payment provider renames a field in its API response. The bug occurs only where the environment differs, so the code passes every review. Many of these reach production first, because staging environments rarely match the full spread of devices and service versions real users run.
Time pressure and process gaps: 14%
The smallest category amplifies the other three. Compressed regression cycles and skipped reviews before a deadline let defects from every other category slip through. Knight Capital’s 2012 loss, covered earlier, started with exactly this kind of deployment gap. Automated testing in CI narrows the gap because it keeps running when the schedule shrinks.
A QA process built only around code-level checks covers about a third of where bugs come from. Teams that want to find bugs early need testers involved from requirements review through production monitoring, the focus of the prevention steps later in this article.
Bug Severity vs. Priority
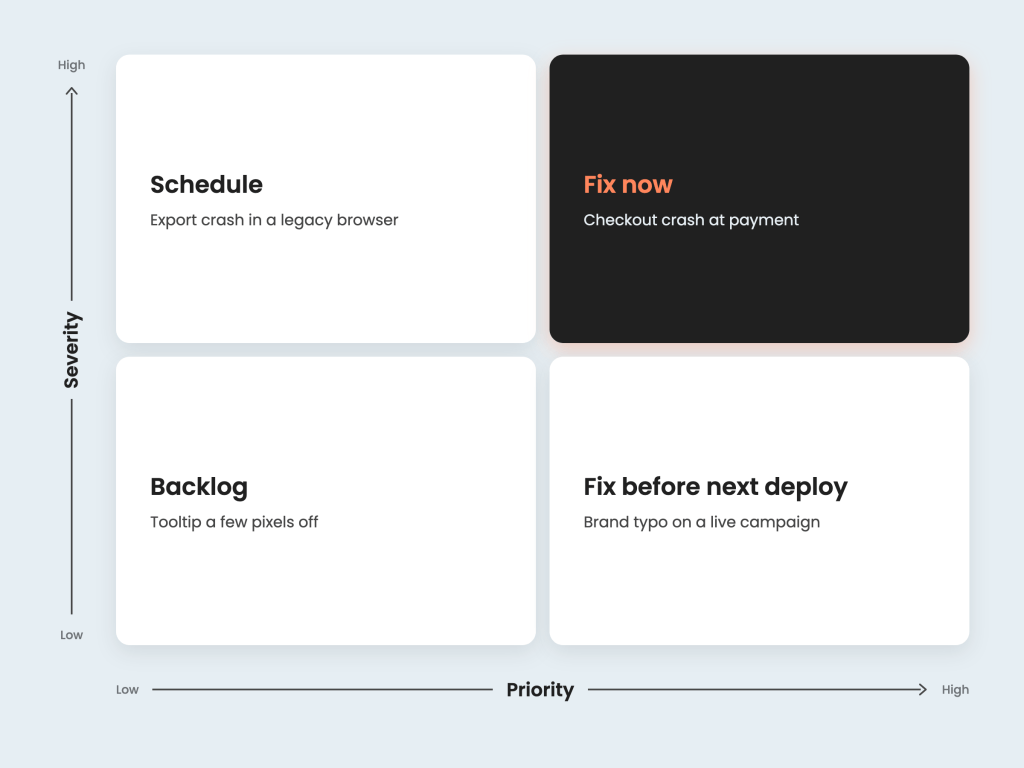
Bug severity refers to how damaging a bug is to the product; bug priority indicates how soon the bug needs to be dealt with. These are two of the most common terms used in bug tracking and can be found in most bug reports. Here is how to better understand the difference between bug severity and priority.
Severity describes how much damage a bug does to the software. Priority describes how soon the team needs it fixed. QA engineers usually set severity from technical impact, and product owners set priority from business context, so the two can point in opposite directions. Most teams grade severity on a four-level scale running from critical through major and minor down to trivial. Priority often uses a shorter scale tied to the release plan.
High priority
Low priority
High severity
Checkout crashes for every user at the payment step. Fix immediately.
A report export crashes in a legacy browser version almost nobody uses. Schedule for a later release.
Low severity
The brand name is misspelled on the landing page of a live campaign. Fix before the next deploy.
A tooltip sits a few pixels off on a settings page. Add to the backlog.
Here is what that can look like for a real software product.
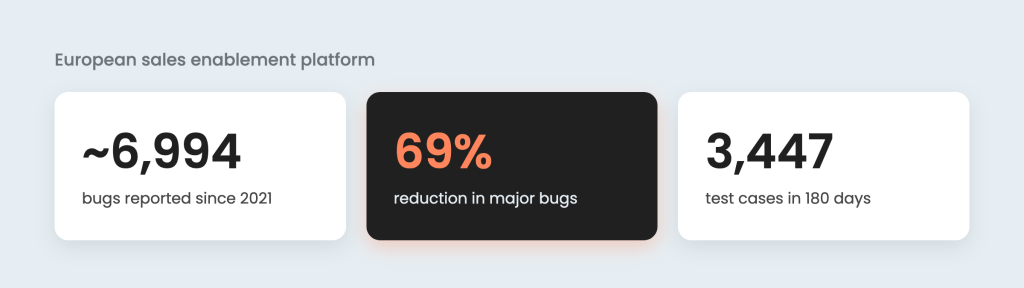
How TestFort Cut Major Bugs by 69% for a Sales Enablement Platform
The client, a European provider of a sales enablement and engagement platform, brought TestFort in as its primary manual QA team. Sales reps use the platform to present product content to buyers, including videos and 3D visualizations, and every feature has to work both online and offline. The same content also has to render on iOS, Android, and Windows-based mobile devices, plus four desktop browsers on Windows and Mac. That made environment-related bugs the main risk on this project.
A dedicated team of 10 manual testers and a team lead built a device matrix of more than 20 mobile devices, from iPads and iPhones to Android tablets, along with 11 computers. Coverage ran from functional and regression testing to localization and load testing. To catch elusive bugs, the team paired detailed step-by-step test cases in Xray with ad hoc testing, which tends to surface the hard-to-reproduce issues that scripted cases miss. Here is what we achieved on the project.
How to Prevent Software Bugs
Preventing bugs is about matching each check to where the bugs actually start. This helps limit the frequency and damage of software errors and system failures. Here are a few strategies to make sure fewer bugs occur at any stage of the software development life cycle:
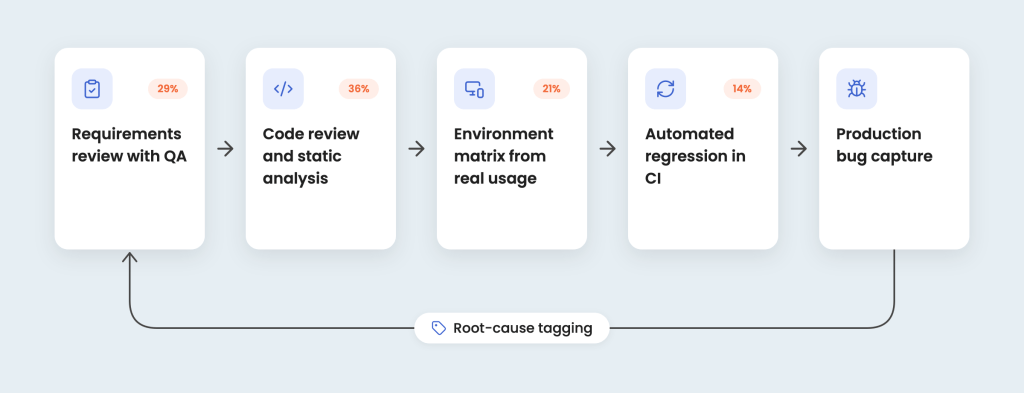
Review requirements with QA before development starts. Testers turn acceptance criteria into test cases while the feature is still a ticket, so ambiguities surface in a planning meeting instead of in the bug tracker. This targets the 29% of bugs that trace back to requirements and communication gaps.
Run static analysis and code review on every merge. Pair them with unit tests on calculation and boundary logic, where design and coding errors (36% of the sample) cluster most.
Build the test environment matrix from real usage data. Product analytics show which devices, browsers, and OS versions customers actually run. Contract tests on third-party APIs catch provider changes before users do. Together, they cover the 21% of bugs that come from outside the codebase.
Protect regression time in the release plan. An automated regression suite in CI keeps running when the schedule shrinks, so time pressure stops letting defects from the other three categories through.
Capture production failures with full context. Bug capture tools that record logs, device details, and the user’s steps turn a vague complaint into a reproducible report, which matters most for heisenbugs and other environment-dependent failures.
Teams that tag every closed bug with its root cause can then measure which of these steps actually improves software quality on their project. If the share of environment bugs falls after a device matrix update, the update worked.
Most delivery and QA teams already know the common types of software bugs. Fewer of them know which root cause produces most of the bugs on their projects. Tagging every new bug with its cause does add a few minutes per ticket, but the effort pays off within a few releases, giving teams clarity and gradually lowering the number and severity of bugs.
Words by
Mykhailo Tomara, QA Lead
“A QA may have a clear reproduction scenario for a bug, while a developer with access to the code will be able to trace specific exceptions to specific lines. Root cause analysis of complicated bugs is where the cooperation between both Dev and QA teams is especially important.”
The bug life cycle is the sequence of statuses a bug moves through from discovery to closure. A typical flow runs new → assigned → fixed → retested → closed, with side branches for reopened, deferred, and rejected bugs.
Which bug tracking tools do QA teams use?
Jira is the most common choice, followed by Azure DevOps, YouTrack, Linear, and GitHub Issues. Test management add-ons such as Xray link each bug to the test case that found it.
Why do software bugs occur even after testing?
Testing reduces risk, but it can’t cover every combination of input, environment, and timing. Bugs that depend on production conditions, such as heisenbugs and environment-specific failures, often appear only after release.
Can software be completely bug-free?
For any nontrivial product, no. ISTQB lists “exhaustive testing is impossible” among its core testing principles. The realistic goal is zero known critical bugs at release, plus monitoring that catches new ones quickly.
Who fixes bugs: testers or developers?
Developers fix bugs. Testers find them, document how to reproduce them, and retest the fix. When a bug starts in the requirements, the product owner updates the spec as well.
Share:
Jump to section
Give your product quality a boost with expert-level testing and QA
Inna is a content writer with close to 10 years of experience in creating content for various local and international companies. She is passionate about all things information technology and enjoys making complex concepts easy to understand regardless of the readers tech background. In her free time, Inna loves baking, knitting, and taking long walks.
Michael has more than 10 years of experience in software testing and a strong technical background in e-commerce, telecom, and customer support projects. He excels in creating, reviewing and maintaining project documentation from requirements and functionality descriptions to test plans and checklists.


 What is the bug life cycle?
 What is the bug life cycle?